Most SEO professionals treat rank tracking as a black box. You input a keyword, and a number pops out. However, when a client questions why your report shows them at position three while their smartphone shows them at position five, the "black box" becomes a liability. Understanding the underlying mechanics of how these tools fetch, parse, and report data is the only way to defend your reporting and make informed procurement decisions. Understanding the underlying mechanics of these tools is key, and it helps to know what a rank tracking tool is in the first place.
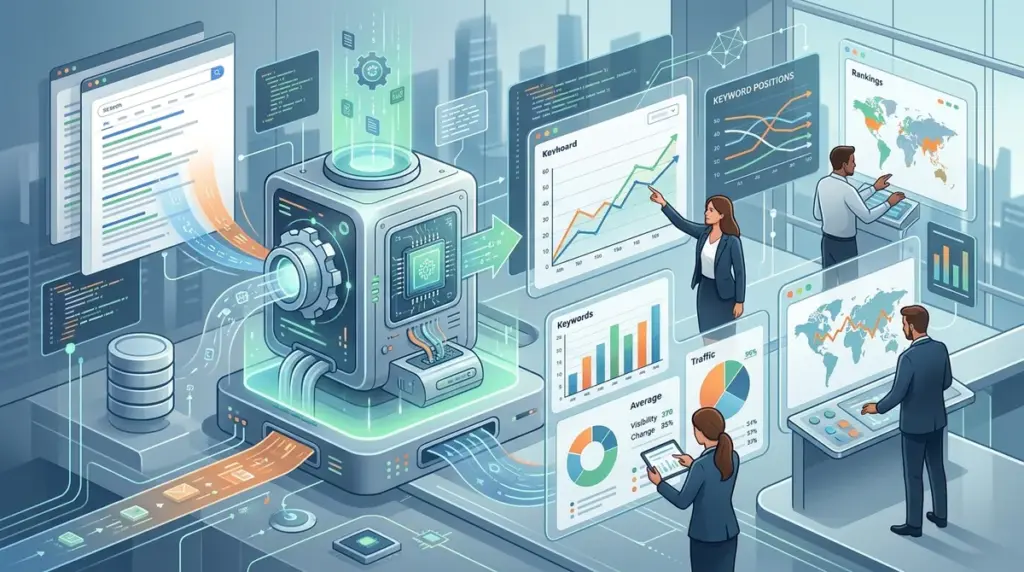
Rank tracking is not a simple matter of Google searching. It is a complex engineering feat involving distributed proxy networks, headless browser rendering, and sophisticated HTML parsing. Here is how the process works from the moment you add a keyword to the moment it appears on your dashboard. Here is how the process works from the moment you add a keyword to the moment it appears on your dashboard, showing what a good tool does.
The Architecture of a Data Request
When you trigger a rank check, the tool does not simply send a request from its own server. If it did, Google would immediately flag the IP address for bot-like behavior and serve a CAPTCHA or a block page. To mimic human behavior, tracking tools utilize massive networks of proxies.
Proxy Networks and Geo-Location Bypassing
To provide accurate local rankings, tools must appear to be searching from a specific city, zip code, or even a specific street corner. This is achieved through three types of proxies:
- Datacenter Proxies: Fast and inexpensive, but easily detected by Google's security layers. High-end tools use these sparingly or for high-volume, non-sensitive checks.
- Residential Proxies: These use IP addresses assigned to real households. They are much harder to detect but significantly more expensive to maintain.
- Mobile Proxies: Essential for tracking mobile-specific SERPs, these routes traffic through cellular networks to simulate a user on a 4G or 5G connection.
The tool selects a proxy matching your target location, sets the browser's language headers to match the locale, and transmits the search query. This ensures the results are not tainted by the tool's physical server location.
Headless Browsers and JavaScript Rendering
Modern search results are no longer static HTML. They are dynamic environments where elements like "People Also Ask" boxes, map packs, and image carousels load asynchronously. To capture this, professional trackers use "headless browsers"—software like Puppeteer or Playwright that runs a version of Chrome or Firefox without a user interface.
This allows the tool to render the page exactly as a human would, executing JavaScript and waiting for all elements to load before "scraping" the data. Without this step, the tool might miss sophisticated SERP features that push organic links further down the page.
Warning for Agencies: Cheap tracking tools often skip full JavaScript rendering to save on server costs. This results in "ghost rankings" where the tool reports a position of 4, but because it didn't render the four-pack of ads and a "People Also Ask" box at the top, the actual organic position is effectively 9 or 10.
Parsing the Document Object Model (DOM)
Once the page is rendered, the tool must "read" it. This is called parsing the DOM. This is the most fragile part of the process because Google frequently changes its CSS classes and HTML structure to thwart scrapers.
A high-quality rank tracker doesn't just look for your URL; it maps the entire SERP. It identifies which elements are organic links, which are paid ads, and which are "SERP Features." It then calculates your "true" position. For example, if you are the first organic result but there are two ads, a featured snippet, and a map pack above you, your "Rank" might be 1, but your "Visual Rank" or "Pixel Height" is much lower. Advanced tools now track the pixel depth of your result to provide a more realistic view of visibility.
Data Refresh Cycles and Latency
There is a constant tension between data freshness and cost. Real-time tracking is computationally expensive. Most tools operate on a 24-hour refresh cycle, meaning the data you see today was actually pulled at a specific timestamp in the last 24 hours.
Best for high-stakes campaigns: Tools that offer "On-Demand" updates. This allows you to force a refresh during a site migration or a major algorithm update, bypassing the standard queue. For standard monthly reporting, 24-hour or even weekly updates are usually sufficient to identify trends without inflating software overhead.
Calculating Share of Voice and Weighted Metrics
Raw ranking numbers are often misleading. Being at position 1 for a keyword with 10 monthly searches is less valuable than being at position 10 for a keyword with 10,000. Behind the scenes, the tool's database merges your ranking data with search volume estimates (often pulled from Keyword Planner or clickstream providers).
The tool then applies a "Click-Through Rate (CTR) Model." It assumes position 1 gets ~30% of clicks, position 2 gets ~15%, and so on. By multiplying these percentages by the search volume, the tool calculates "Estimated Traffic" or "Share of Voice." This is a synthetic metric, but it is far more useful for business reporting than raw rank alone because it accounts for the commercial weight of each keyword.
Auditing Your Tool’s Data Integrity
To ensure your tool is providing accurate data, you should periodically perform a "clean room" search. Open an Incognito window, use a VPN or a browser extension to spoof your GPS location to match your target area, and search for your primary keywords. If the tool consistently deviates by more than two positions, it likely has an issue with its proxy localization or its ability to render modern SERP features.
Furthermore, look for tools that provide a "Snapshot" or "HTML View." This is a saved image or code file of the exact SERP the tool saw when it recorded the rank. This is your "receipt" and is invaluable for proving to clients that a ranking drop was caused by a new competitor or a change in Google’s layout rather than a failure of your SEO strategy.
Frequently Asked Questions
Why does my rank tracker show different results than my own Google search?
Google personalizes results based on your search history, logged-in account, and precise IP location. Rank trackers use "clean" sessions with no history and specific geo-proxies to provide a neutral baseline that represents what a new user in that area would see.
What is the difference between organic rank and absolute rank?
Organic rank counts only the blue links. Absolute rank counts every element on the page, including ads, map packs, and snippets. If there are four ads above the first organic result, the organic rank is 1, but the absolute rank is 5.
Can Google block rank tracking tools?
Yes. Google uses sophisticated bot-detection patterns. This is why professional tools constantly rotate their proxy IPs and use headless browsers to mimic human mouse movements and scrolling. If a tool's proxies are "burned" (blacklisted), you may see gaps in your data or "N/A" results.
How often should I refresh my keyword data?
For most businesses, daily updates are the standard. However, for e-commerce sites during peak seasons (like Black Friday) or news publishers, hourly updates may be necessary to react to rapid market shifts. For long-term brand building, weekly updates are often enough to see the "signal" through the daily "noise" of SERP volatility.